In brief
Twitch has introduced a new setting that lets streamers block Amazon from harvesting their content for AI training. The feature flips Amazon’s default data-collection behavior, giving creators control over how their clips, chat logs and images are used. Users who remaining enabled will still provide data, but it will not be resold. The move comes amid backlash over privacy and marks a shift in how virtual platforms handle AI exploitation.
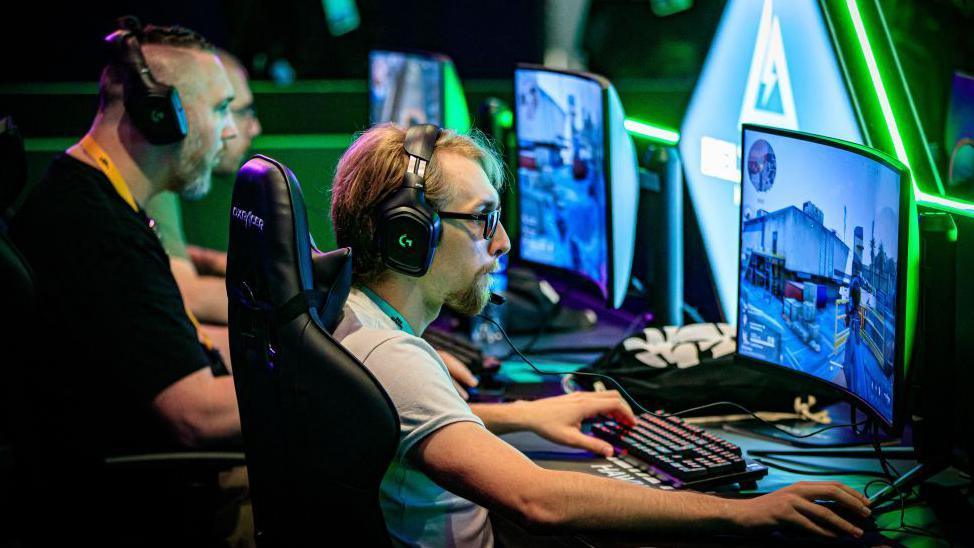
On Wednesday, Twitch announced that users can now block Amazon from using their video streams, clips, images and chat logs to train generative artificial‑intelligence models. The platform’s default settings had previously enabled data collection without explicit consent, a practice that sparked strong backlash from the streaming community.
Amazon, which owns Twitch, leverages the content it gathers to improve its AI services and compete with rivals like Google and Meta. Chief product officer Mike Minton told users that if the feature were opt‑in, “nobody would opt‑in” and that the data held will not be resold to other companies.
Streamers who keep the setting enabled may still use the data for AI training, but can now choose to disable it through channel settings. Head of community Mary Kish walked viewers through the process in a tutorial and acknowledged that the industry is normalising data collection for AI. She noted, “We don’t expect anyone to react favorably,” while warning that “the stream’s chat column was flooded with criticism.”
The decision raises questions about ownership of digital creative output in a metaverse‑centric world. As more platforms adopt AI‑driven personalization, content creators demand transparent control over how their work fuels algorithmic models. Twitch’s opt‑out reflects a broader push toward respecting creator autonomy amid the growing commercialization of their virtual presence.
To opt out, streamers can navigate to their channel settings, find the “Generative AI training” toggle, and switch it off. Meanwhile, the industry will likely examine how similar policy changes might shape the future of virtual production, streaming, and the relationship between creators and the AI services that consume their data.